Supervised fine-tuning
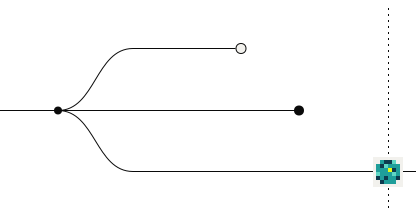
We fine-tune on examples that pair representative inputs with the outputs we want the model to produce.
A model can earn a higher reward and still produce worse outputs. We design training objectives and evaluations together to test whether the model learns the intended behavior and retains the capabilities the application depends on.
We fine-tune on examples that pair representative inputs with the outputs we want the model to produce.
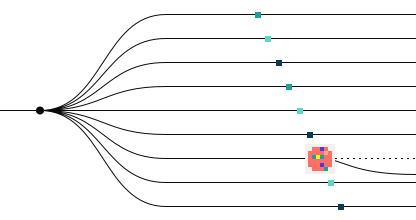
We generate rollouts and score the model’s outputs with a reward function. Those scores guide the next update.
We define what success looks like, then compare checkpoints with the base model and any current production model using the same held-out inputs and settings.
We check for regressions on inputs beyond those used to evaluate the target behavior. For video, we check whether scene content, motion or sharpness has changed.
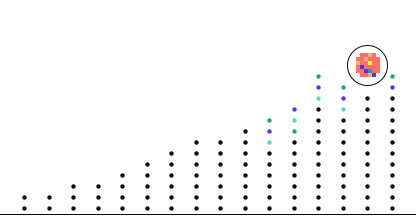
We inspect outputs, including high-scoring ones, for failures the metrics miss. We document what the evaluation leaves untested.

