Hedra
  • Developers
  • Inference
  • Studio
  • Enterprise
Log inSign Up
Open Hedra
Your account
    Explore
  • Home
  • Developers
  • Inference
  • Studio
  • Enterprise
    Log inSign Up
    Open Hedra

Make an AI talking avatar from one photo.

No camera, no booking. Give a portrait a script and a voice and it performs — in any language, for as long as the audio runs. For ads, training, localization, and the presenter inside your own product.
Start building nowMake one now — no code
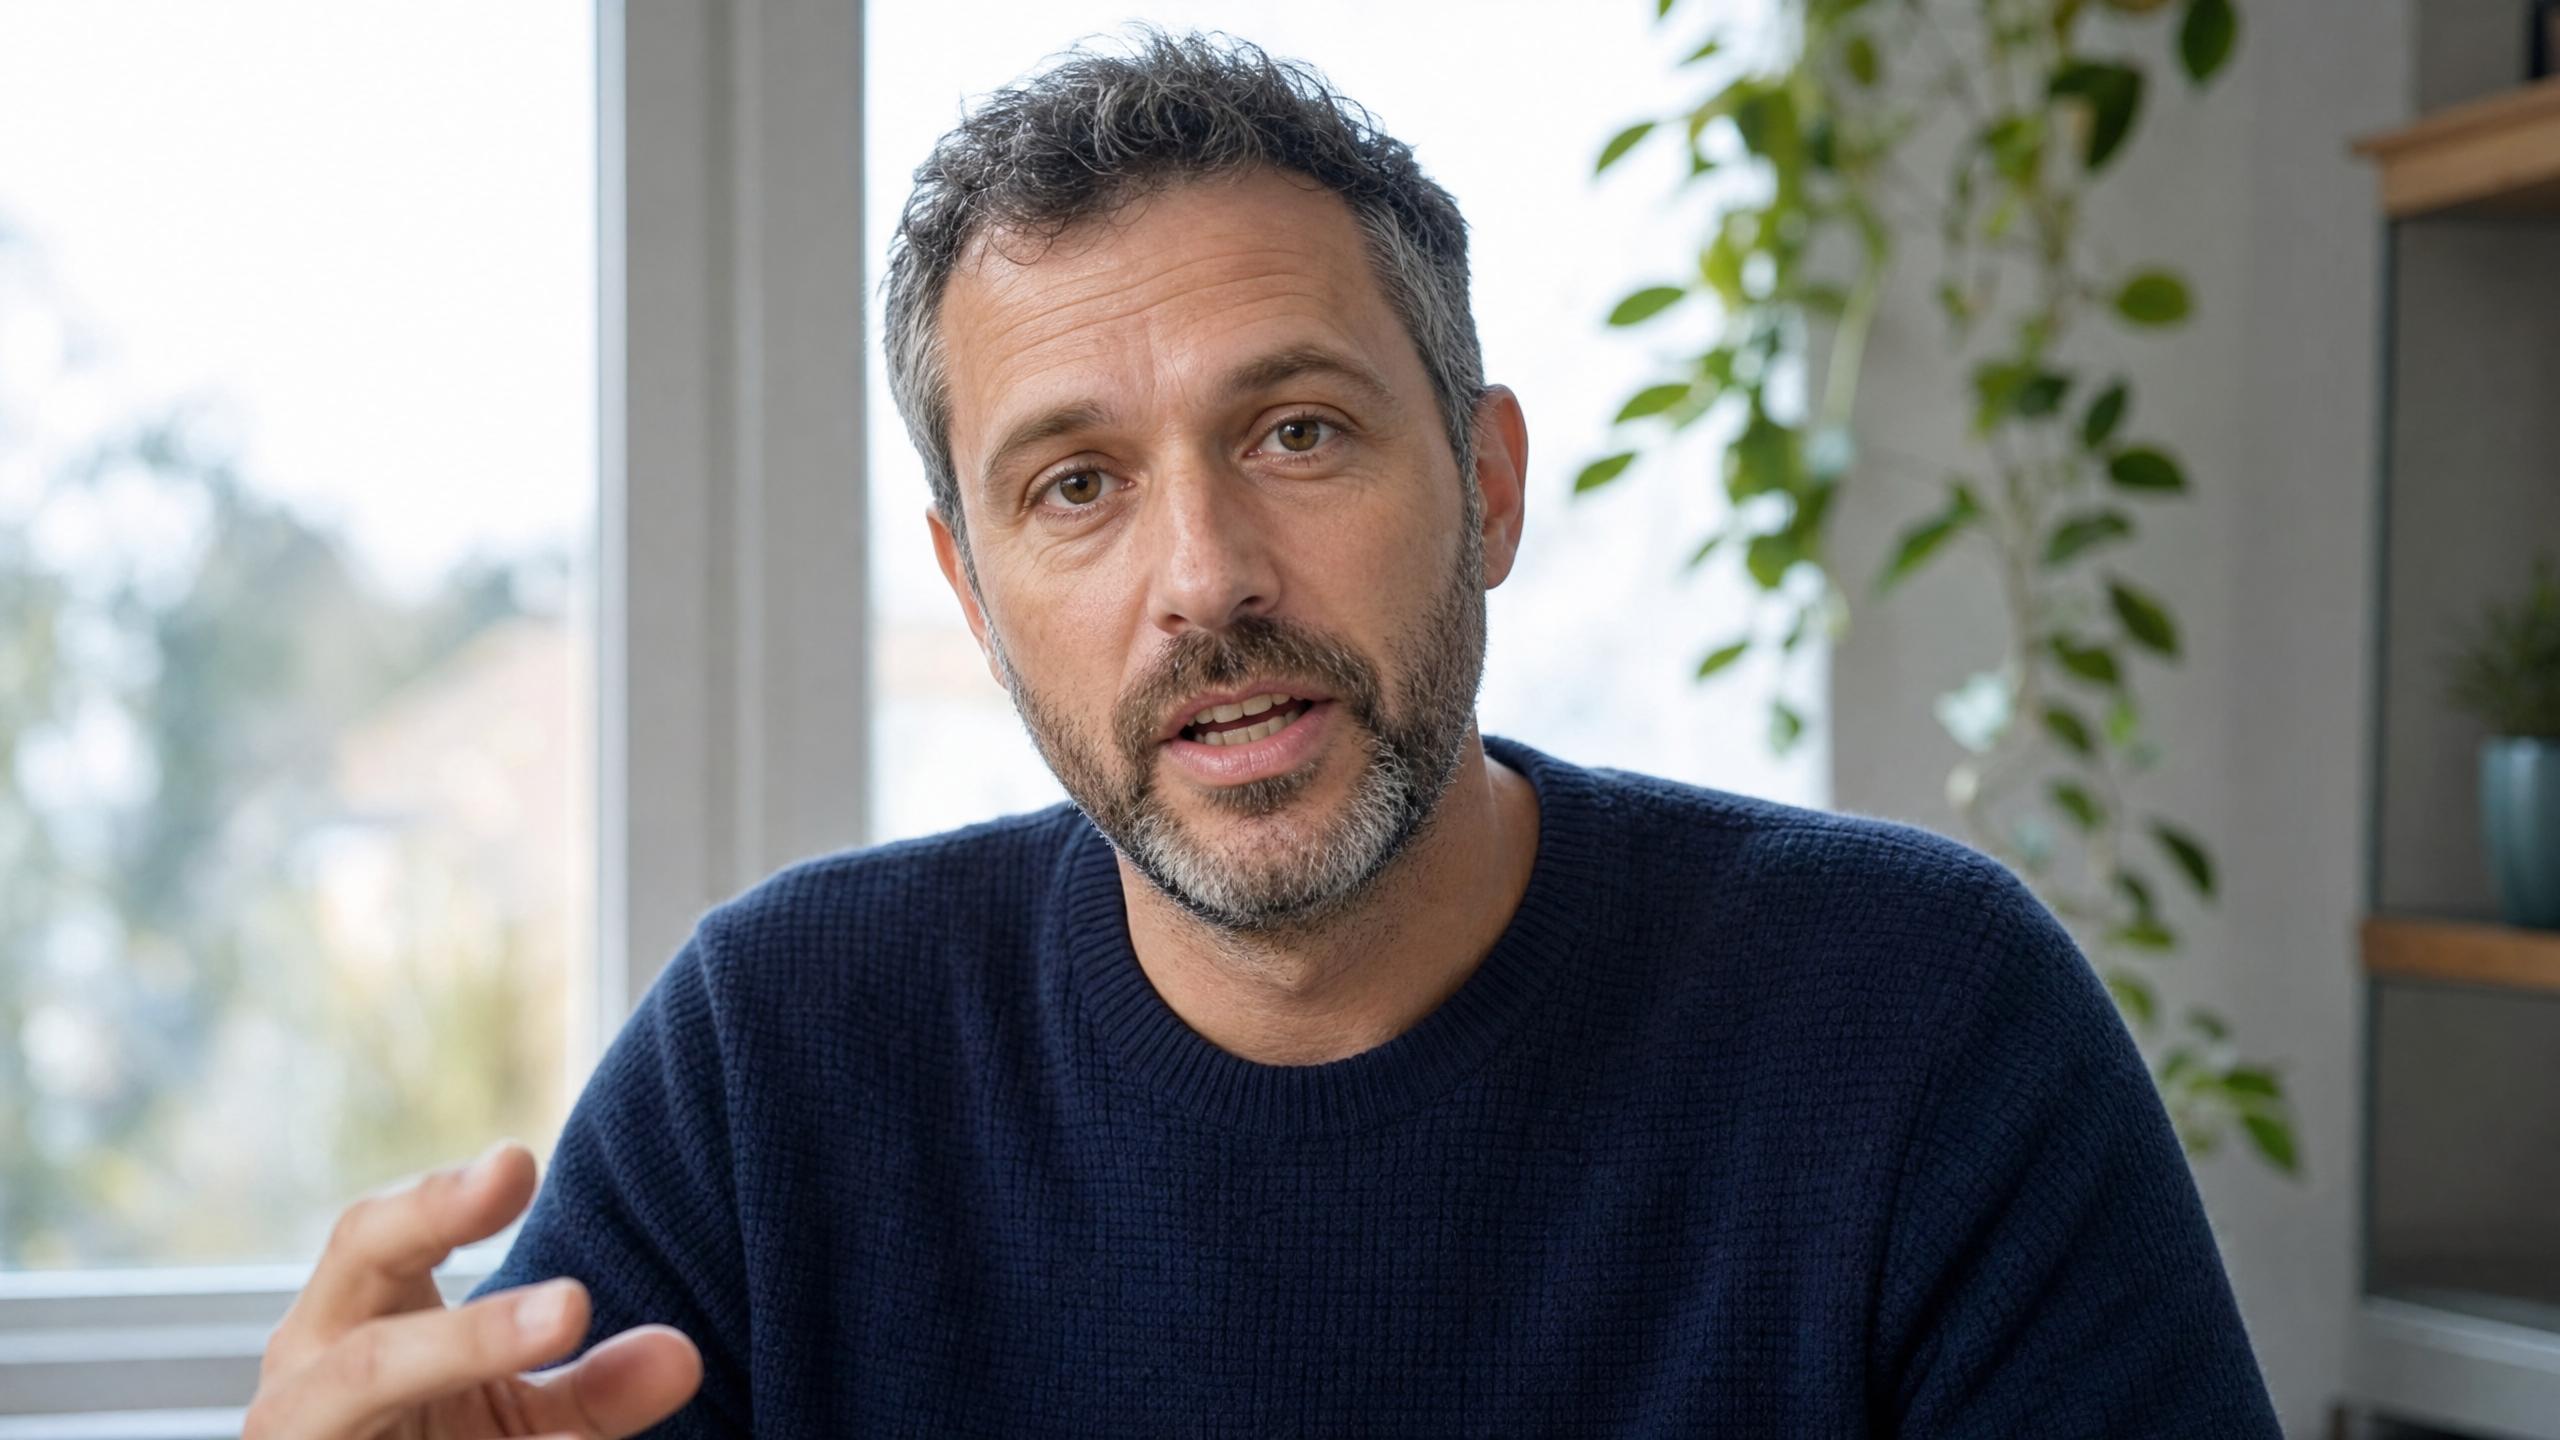
Photo + script in
A bearded man in a navy sweater gesturing as he talks to camera by a window with hanging plants

"We rebuilt onboarding this quarter. Let me show you what changed."

PNG · 2560 × 1440
→

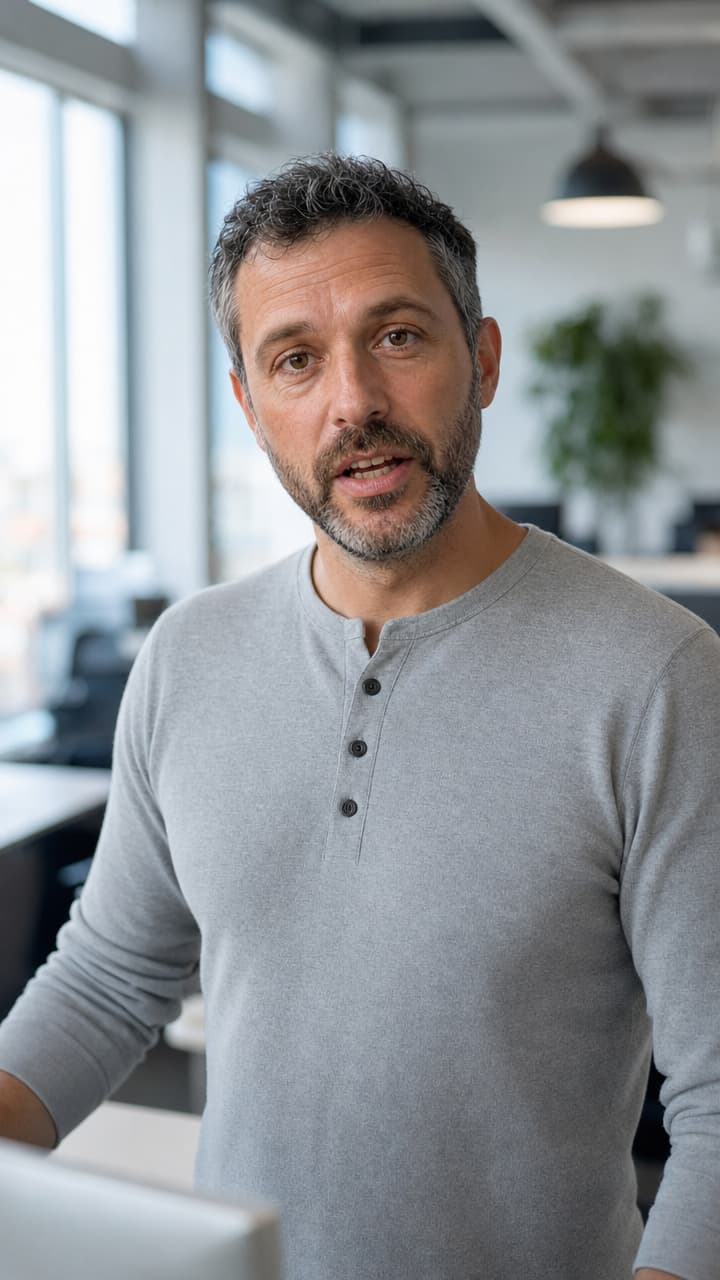
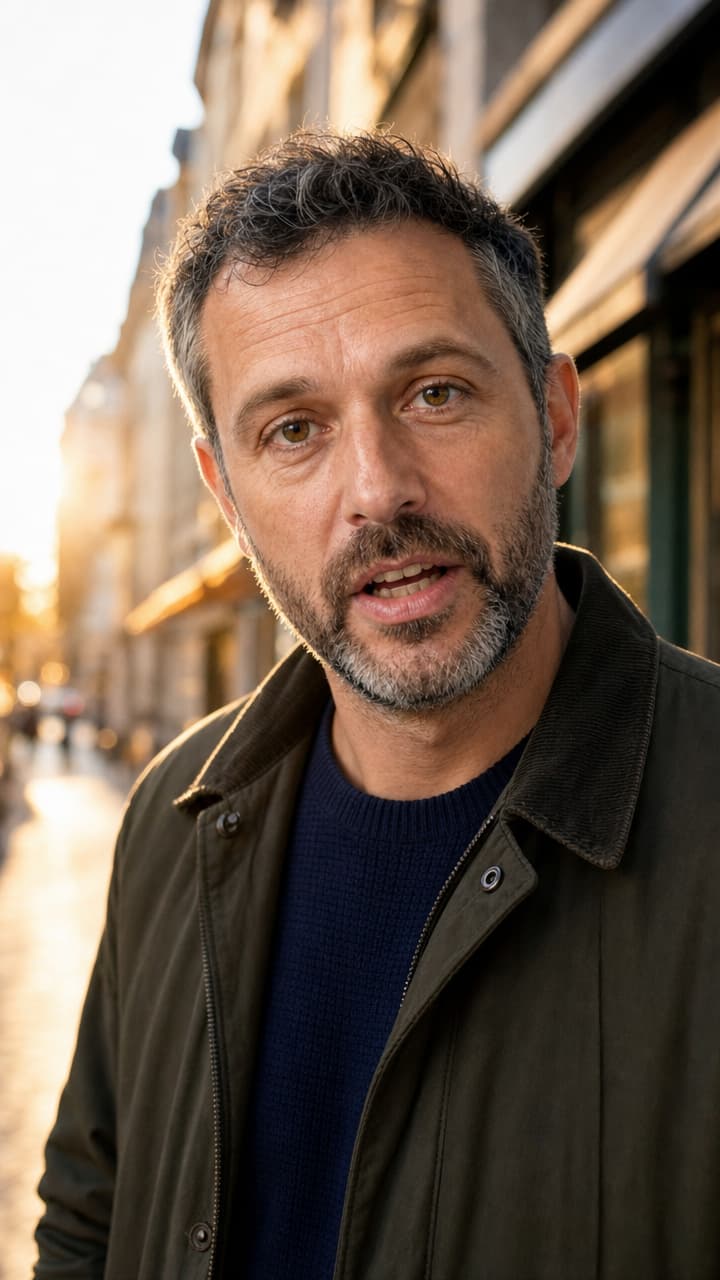
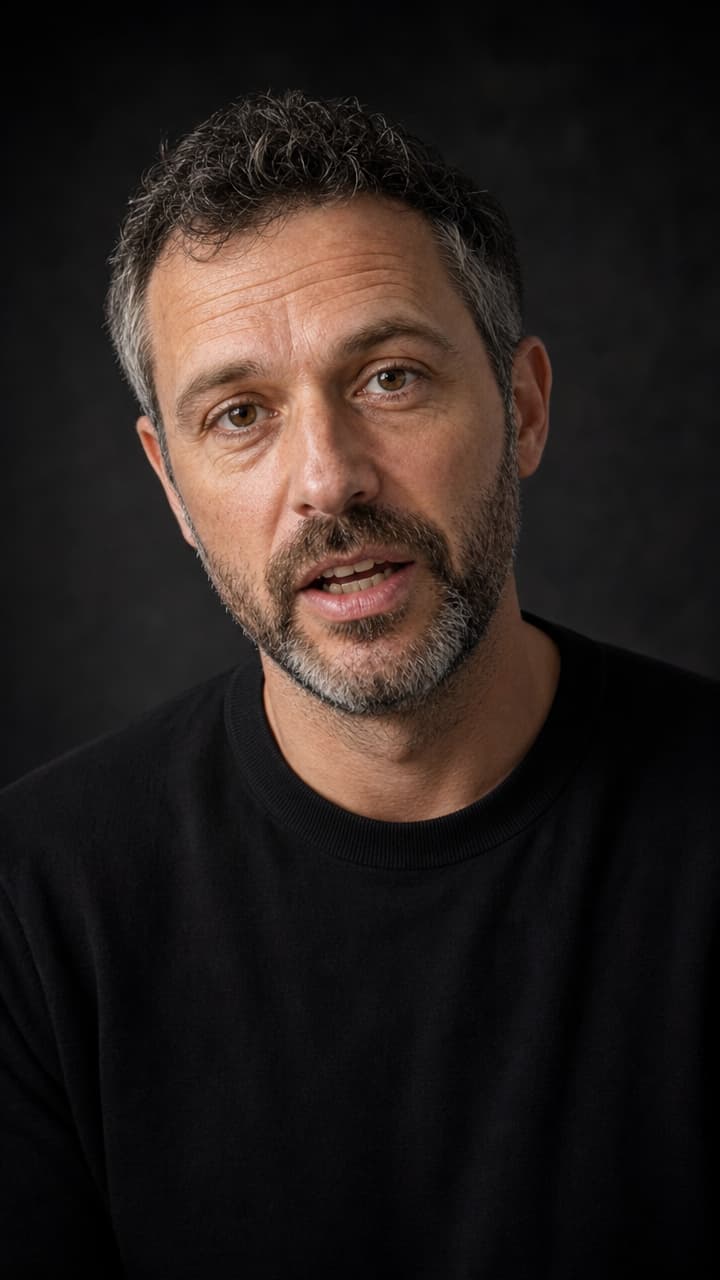
The same person, on demand.

A bearded man in a gray henley speaking to camera in a bright open-plan office
A bearded man in a dark jacket speaking to camera on a sunlit city street
A bearded man in a black sweater speaking to camera against a dark studio backdrop
ONE PORTRAIT · EVERY SETUP

The same face, every take.

Lock the portrait once and it holds — through a script you rewrote this morning, a module you add next month, a market you open next quarter. That's what turns a clip into a spokesperson: a campaign, a course, or the presenter inside your own product can all wear the same face without a second shoot. It's also what makes testing cheap, because ten hooks for TikTok, Reels and YouTube cost ten renders rather than ten shoots.

“Wir haben das Onboarding komplett neu gebaut.”VEO 3.1 · 0:08 · GERMAN

Every market, the same face.

Swap the audio and keep the person. The same portrait delivers your script in whatever language the market speaks, so localization stops being a reshoot and becomes a file you drop in — a voice you picked in Studio, or another audio URL in the request.

“The pilot wrapped last week.” · “And the numbers held.”VEO 3.1 · 0:08 · TWO SPEAKERS

Two people, one frame.

Point one portrait at one audio track and you get a presenter. Point a two-up frame at two — one per speaker, marked by where each sits — and you get a conversation, each voice landing on its own face with nothing to cut between. Interviews, role-plays, the awkward support scenario every onboarding course needs.

Every avatar and every voice, under one key.

HedraHedraHedra AvatarHedra Character 3
ByteDanceByteDanceOmnihuman 1.5
KlingKlingKling AI Avatar v2Kling V3 Motion ControlKling 2.6 Motion Control
VEEDVEEDVEED Fabric 1.0
ElevenLabsElevenLabsMultilingual V2V3Flash Multilingual V2Voice Clone
MiniMaxMiniMaxSpeech 2.5 HDSpeech 2.5 Turbo
See all models →

Built for visual inference.

Serving video is a different problem from serving text — a single request can saturate a GPU, and none of the tricks that made language models cheap apply. Hedra's engine was built for exactly that workload.

Whichever model you choose — ours or anyone else's — it runs on the same infrastructure, tuned for visual inference and priced per second of output.

Generate with API or Agent

Build with the API

One key, every model, priced per second of output.

Start building now

Make one now.

No code — bring a photo, type the script, pick a voice, export the result.

Create with Agent

FAQs

No. Bring a photo of whoever should present, or generate the character first and use that — the avatar models take a still either way, so nothing has to be filmed and nobody has to be booked.

Generate a character →
Hedra Avatar and Hedra Character 3 are ours; Omnihuman, Kling AI Avatar and VEED Fabric run on the same engine and the same key. Each model page lists the inputs it takes and its per-second rate.

Video models →

It depends on the model. Hedra Avatar runs up to ten minutes from a single audio file, which is why it suits training and long-form; the clip-oriented models are built for the short vertical cuts that social rewards.

Short social video →

Type a script and pick a voice, clone one from a sample you own, record straight in, or upload audio you already have. The ElevenLabs and MiniMax voices run through the same API as the avatar models.

Browse all models →

Yes. Pass one audio track per speaker and mark where each of them sits in the frame, and the performance lands on the right face without cutting between shots.

Yes, on a paid plan — commercial rights and unwatermarked output come with every one of them. The current tiers and what each includes are on the pricing page.

See pricing →

A talking avatar starts from a photo and becomes a speaking performance — the character is the product. A face swap moves one identity into footage that already exists. Reach for an avatar when you are creating the person, and for identity transfer when the performance is already shot.

Talking photo AI →

Yes. One key covers every model, so a whole content pipeline bills per second of output rather than per seat. Talk to us if you need committed capacity, private deployment, or terms.

Hedra for enterprise →

No — Hedra Studio runs the same models on the same engine with nothing to build. Bring the photo, type the script, pick the voice, export the result.

More you can do with Hedra

Honey pouring from a glass jar onto a wooden spoon against a dark background
Animate a still you already haveIMAGE TO VIDEO AI →
A lighthouse keeper in a wool sweater pours tea beside the lantern-room glass as the lamp beam sweeps through fog
Start from a sentence insteadTEXT TO VIDEO AI →
hedra keys create
→ sk-hedra-••••••••
Wire it into your productDEVELOPER PLATFORM →

Put a face on the next thing you ship.

Start building nowMAKE A TALKING AVATAR NOW — NO CODE →
Hedra
Hedra

Product

DevelopersStudioEnterpriseInferencePricing

Resources

Agent documentationDeveloper documentationBlogUse CasesModelsFeedbackChangelogStatus

Company

AboutCareersContactBuilder programSupportAlternatives

Legal

Privacy PolicyTerms of useAcceptable useCookie PolicyBiometric data policy
LinkedinInstagramDiscord
support@hedra.comHedra 2026 — All rights reserved