Every model on one key, so the handoffs stop costing you.
The expensive part of working across four vendors is not the inference — it is the downloading, re-uploading, converting and re-referencing between them. Both clips below are ends of the same chain, and nothing was exported in between.
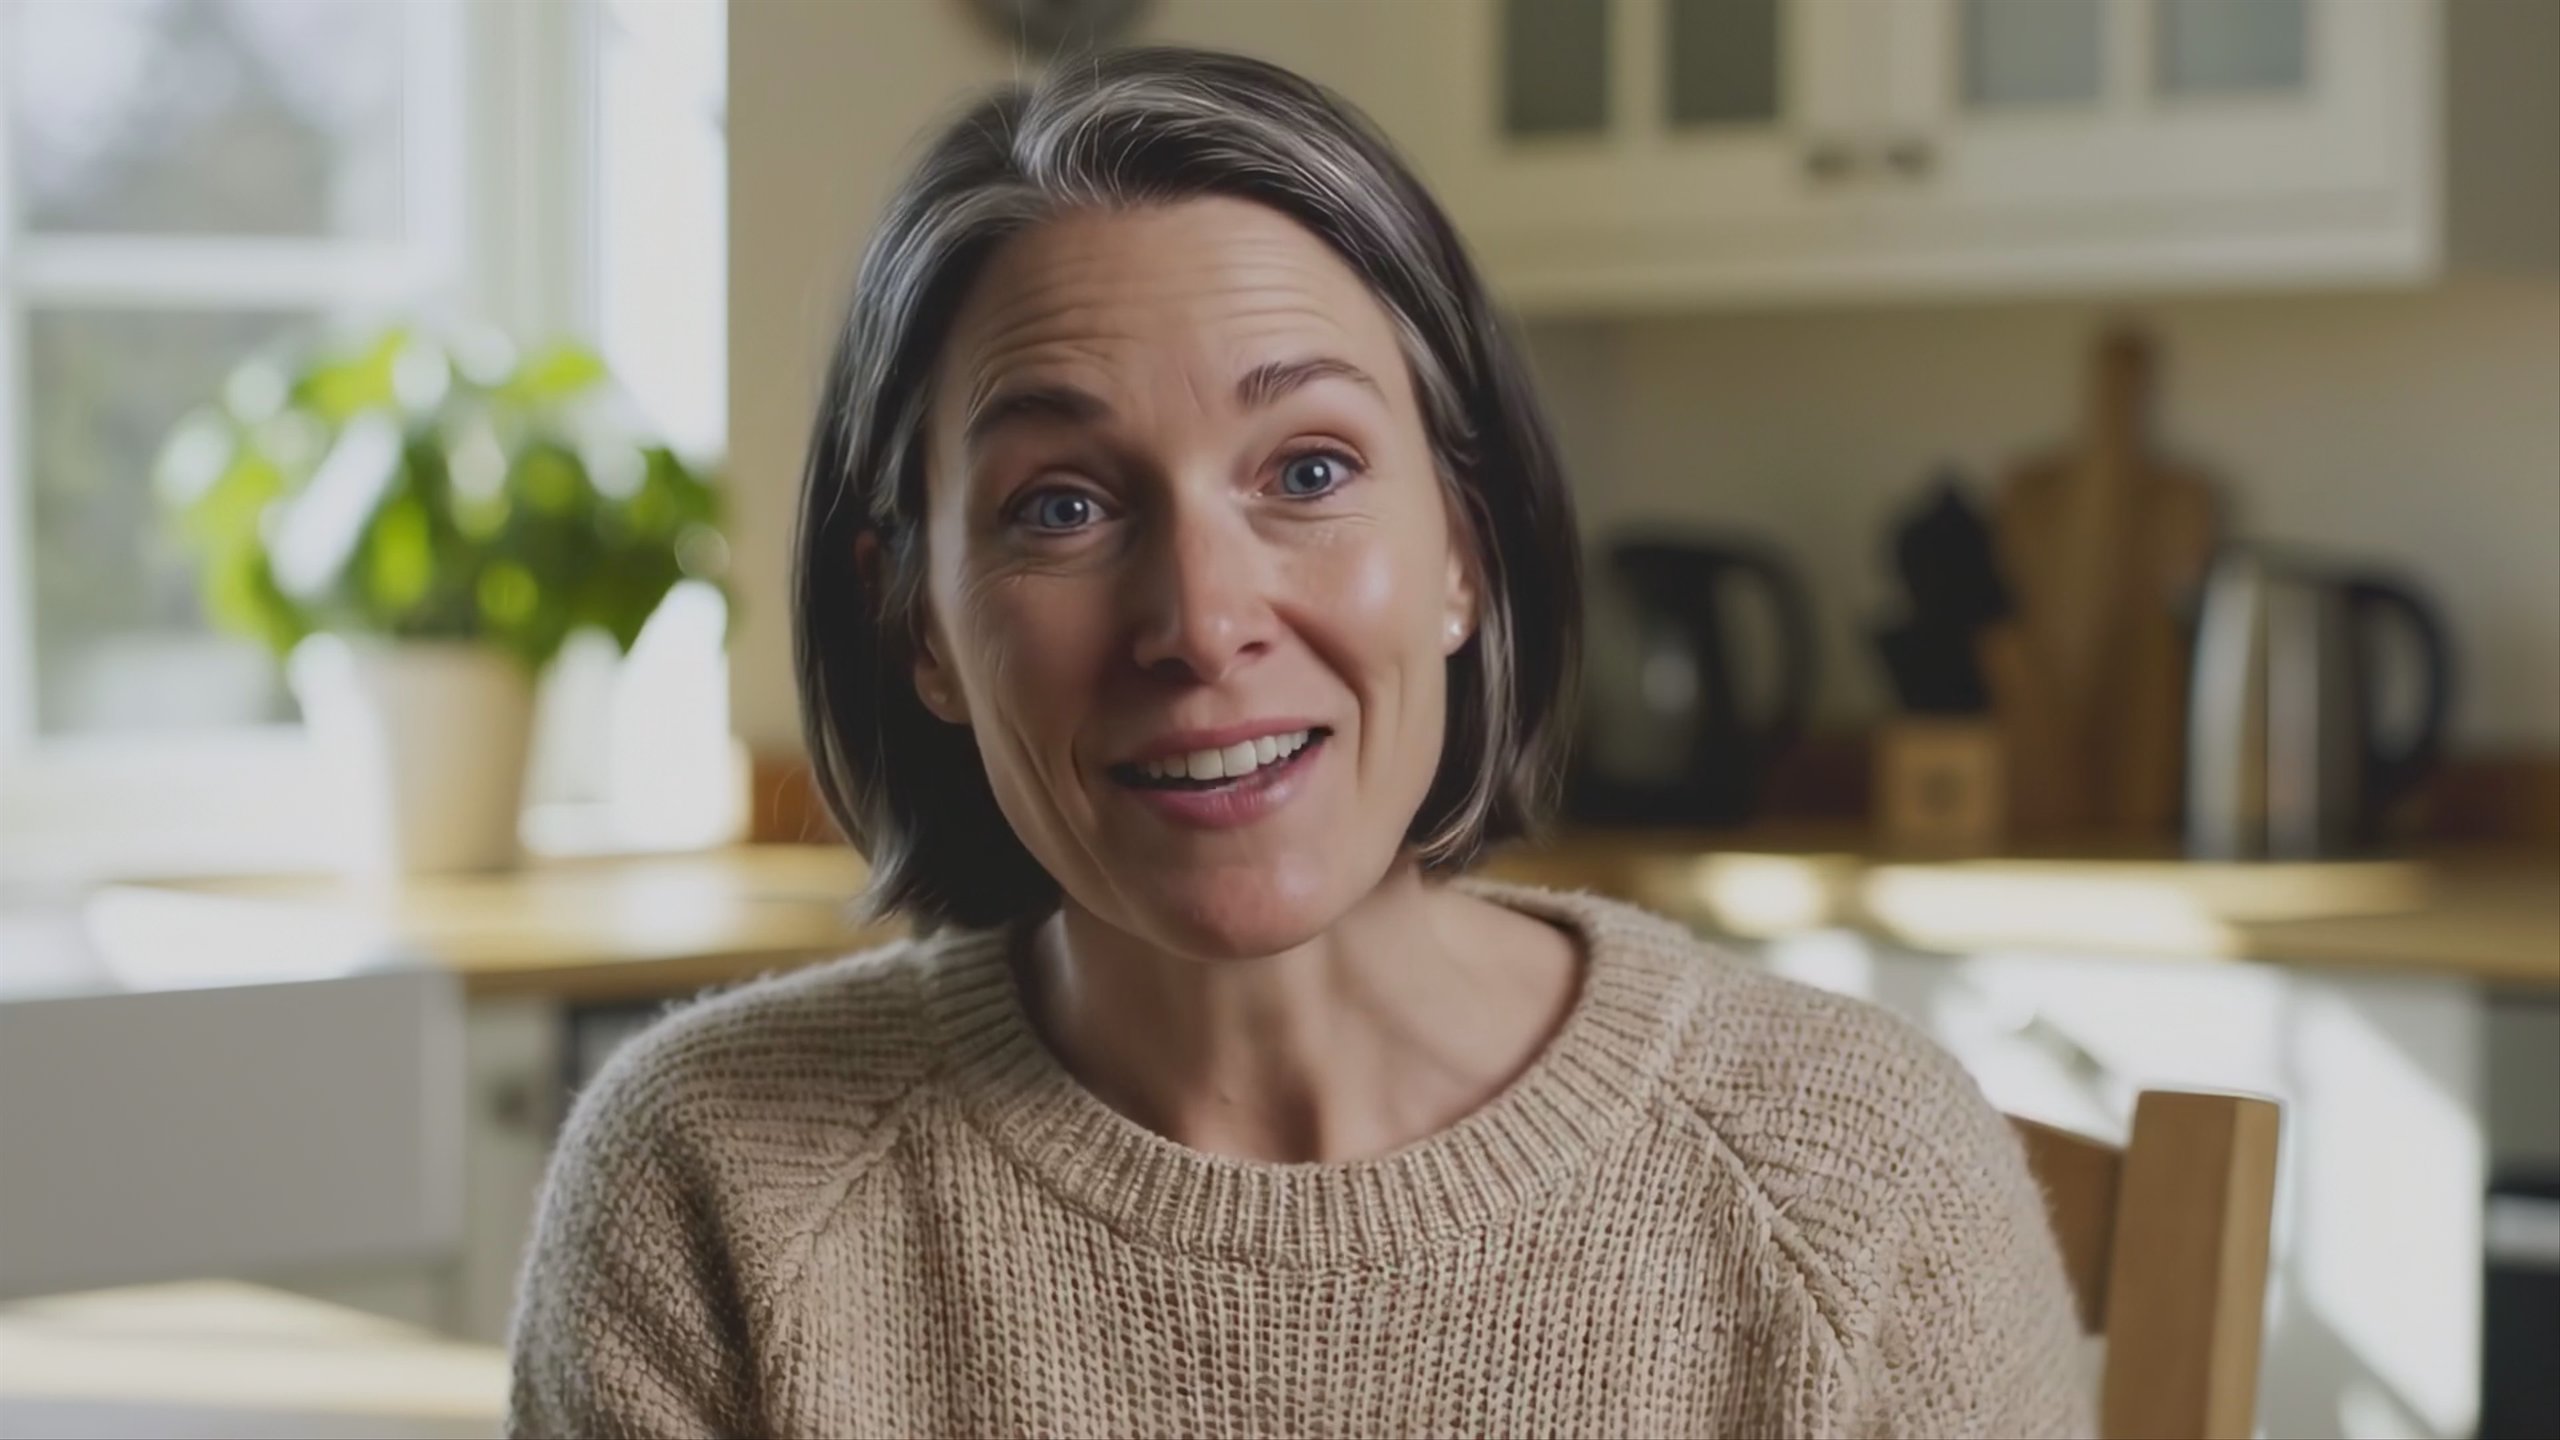
On the left, eight seconds of someone talking. On the right, the same face saying something she never said, in a language she does not speak. Between them: a clip generated, a voice cloned, a script spoken, a face driven. Turn the sound on.
Nothing on this page was made for this page. Every chain here was run while building one of the capability pages it links to — which is the only way a claim about pipelines is worth anything.
The handoffs are the expensive part.
Generate small, finish big, two vendors, one request chain.
This clip was generated at 480p by one maker’s model and finished at 1080p by another’s, with the output of the first passed straight into the second by id. That pattern — render cheap, upscale once, ship — is the difference between a sustainable render budget and an unsustainable one, and it only works if there is no download-and-reupload step in the middle where the file gets re-encoded and the metadata is lost.
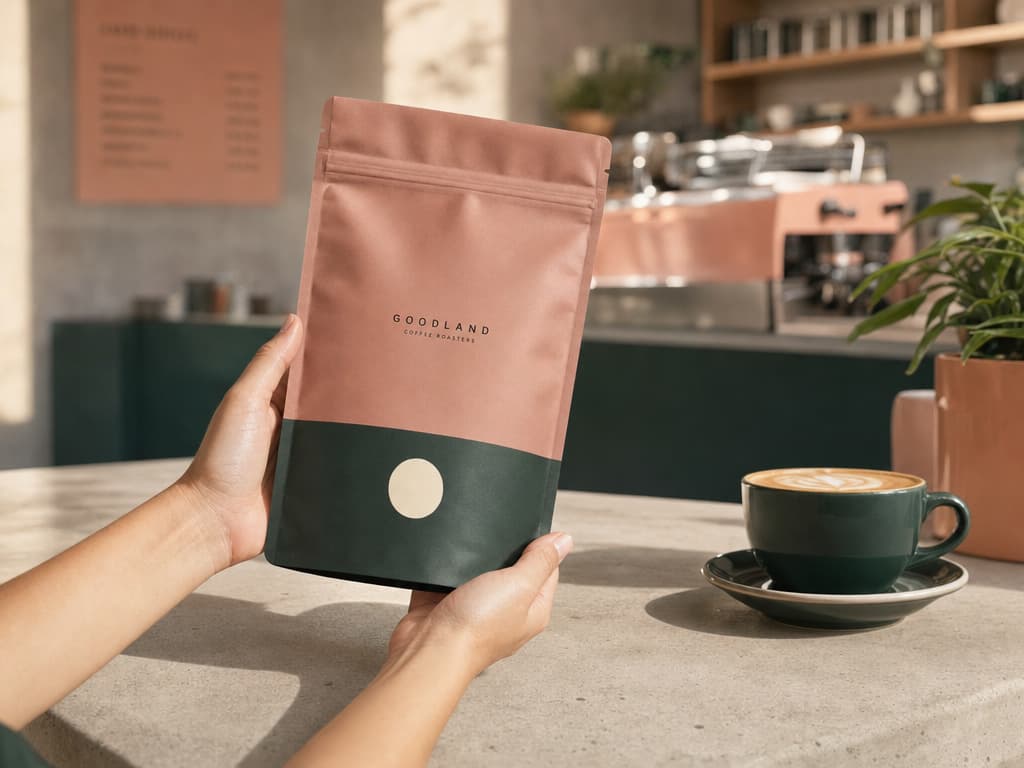
A reference is a thing you keep, not a file you re-upload.
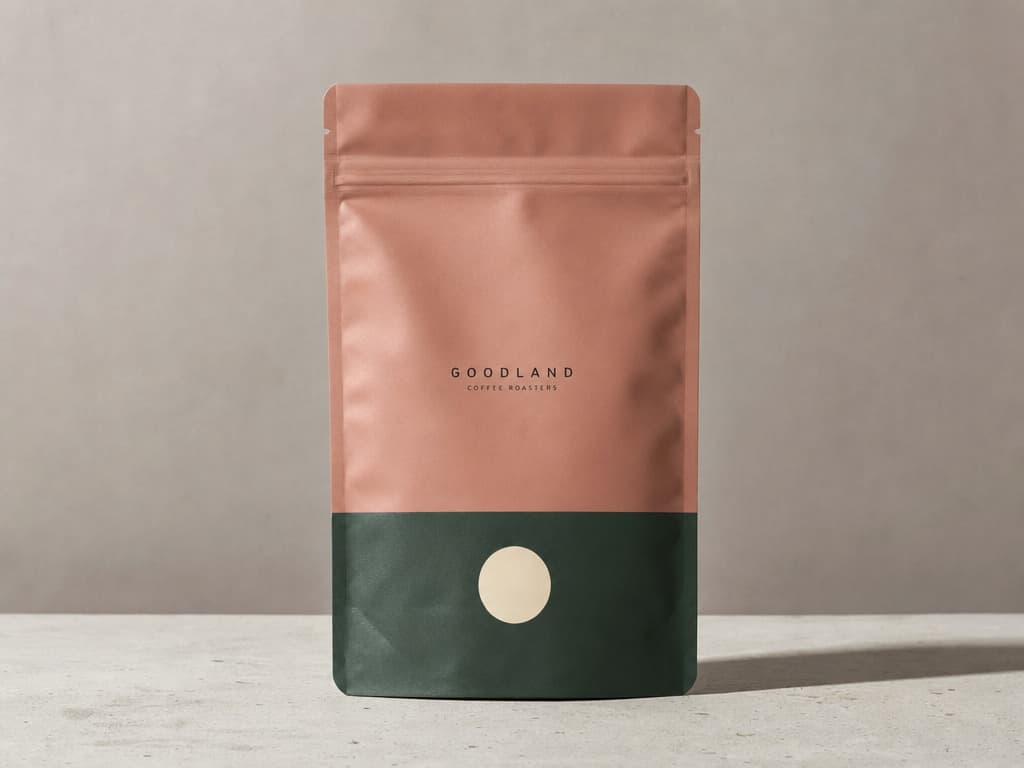
The same is true sideways rather than forwards. This café scene was made from a product shot generated earlier, by passing that image back by id — not by exporting it, storing it somewhere, and attaching it again. Which is what makes a consistent set cheap enough to be worth doing: the tenth asset costs one request, not one request plus the ceremony of finding the reference again.
Different makers. One key, one request shape.
Built for visual inference.
Serving video is a different problem from serving text — a single request can saturate a GPU, and none of the tricks that made language models cheap apply. Hedra's engine was built for exactly that workload.
Whichever model you choose — ours or anyone else’s — it runs on the same infrastructure, behind one key, with the same request shape and the same asset ids. Which is the whole of it: an output is an input, a voice is an id, a reference is an id, and swapping one maker for another is a string rather than a migration.
Generate with API or Agent
Build with the API
One key, every model. Pass outputs straight into the next request by id.
Run a chain now.
No code — ask for the whole sequence in one go and watch it hand off between models.
FAQs
An output is an input. A generated clip can be handed to an upscaler, a voice clone or an avatar model by id, without being downloaded, re-encoded and uploaded again. That sounds administrative until you have built a pipeline across four vendors and discovered that the glue is most of the work.